Listening room
Token counts can badly exaggerate AI costs, but cheaper inference also changes how developers work
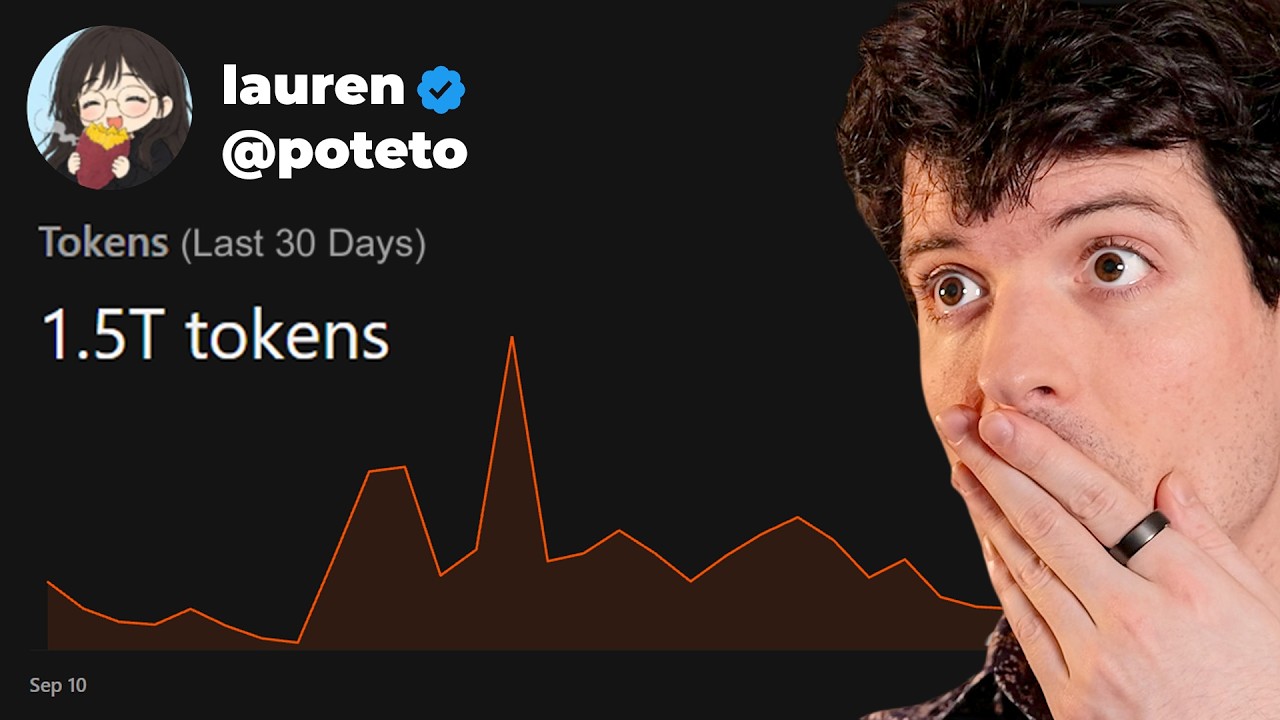
Theo argues that viral estimates of an engineer’s AI token spending misprice aggregate usage by ignoring cached reads, cached writes, model choice and negotiated rates. He presents lower personal estimates and cites benchmark comparisons suggesting that comparable model intelligence has become dramatically cheaper. The transcript also contains a serious qualification: applied tasks may not cost less when newer agents perform more work, use tools and replace human effort. The claims remain largely the speaker’s own calculations and examples.
Editorial summary · Public video captions
What matters
- Aggregate token counts combine differently priced input, output and cached tokens, so multiplying all tokens by a headline rate can overstate costs.
- Theo says falling inference prices are enabling more autonomous workflows, not merely cheaper versions of old prompts.
- The counterargument is that benchmark-equivalent intelligence does not automatically translate into 10-fold cheaper real-world tasks.
- He treats unusually heavy usage as a mix of engineering, product research, marketing and experimentation rather than ordinary employee consumption.
The disputed cost calculation
The video begins with a claim that 1.5 trillion tokens imply $132 million a year. Theo says this applies an average price to an aggregate count and ignores that cached reads may cost far less than ordinary input or output. He estimates the effective spend at roughly $1 million or less, while acknowledging that his own figures are estimates rather than disclosed company accounting.
Why cached tokens matter
Theo says his own usage is dominated by cached reads and writes, while the input and output prices used in the viral calculation represent less than 8% of his spending. He uses this to argue that headline per-million-token rates are not meaningful unless the token categories and model mix are known.
What heavy usage is buying
The speaker describes the engineer’s work as thousands of pull requests, bug fixes and product changes across Cursor and related tools. His argument is that the usage produces software improvements and user feedback, while also generating attention that could have marketing value. These are his observations and estimates, not independently verified productivity results.
The falling price of comparable capability
Theo cites benchmark examples in which newer models achieve similar or higher scores at far lower prices than earlier reasoning systems. He interprets these comparisons as evidence that intelligence at a given benchmark level is becoming cheaper, potentially at an accelerating rate. The transcript does not independently establish the benchmark methodology or the cited model prices.
The applied-AI objection
A competing view in the discussion is that the cost of a practical task may remain similar because modern agents do more: inspect a codebase, run commands, test changes and handle steps previously performed by engineers. Theo accepts that task-level accounting differs, but argues that the human effort removed from the workflow is itself a meaningful gain.
Why old-model comparisons are difficult
Theo says comparisons with models from three years earlier are misleading because reasoning models and tool calls were not yet part of ordinary coding workflows. He instead contrasts an early reasoning model’s performance and cost with later models, while conceding that benchmark scores are imperfect measures of practical outcomes.
The workflow is changing
The central practical claim is that developers are no longer only asking models to edit selected text. They increasingly give agents a goal, a screenshot or a repository and allow them to inspect, modify and test the result. That can increase token use even as the cost of each unit of capability falls.
What the speaker concludes
Theo expects equivalent capability to become much cheaper, but says users will probably spend the savings on smarter models, longer runs and harder tasks. He closes by arguing that unusually expensive experimentation can be rational when it advances products and workflows, while warning viewers to challenge emotional claims that rely on opaque or mismatched numbers.
Context & caveats
- This is a machine-transcribed video transcript; names, model labels, figures and technical terms may contain transcription uncertainty.
- The episode is commentary by Theo, not independent reporting. Many prices, benchmark results, company relationships and productivity claims are presented as personal calculations, recollections or forecasts.
- The transcript includes a sponsor segment, which has been excluded from the notes.
Why this made the edition
The complete transcript contains a substantial practitioner argument about token accounting, inference-cost declines and the difference between benchmark prices and applied engineering outcomes. It is opinionated and relies heavily on the speaker’s own estimates, so quality is moderate.
Source material