Reading room
Claude Haiku 5.5 targets low-cost agent work with stronger benchmark results
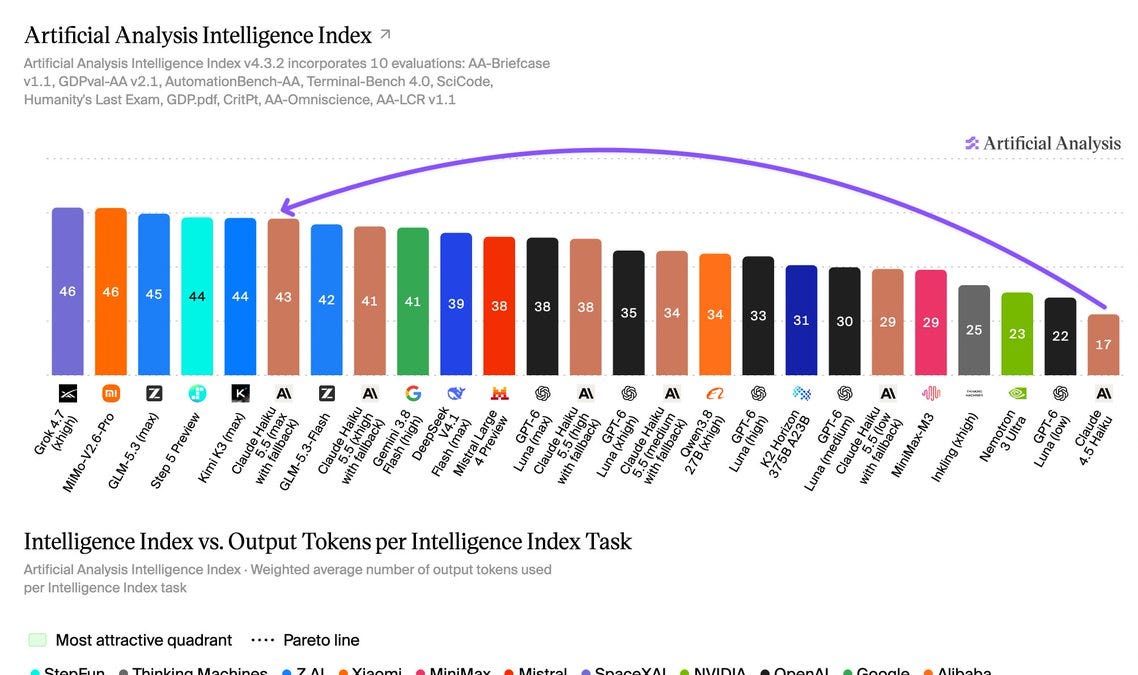
Anthropic's Claude Haiku 5.5 is positioned as a lower-cost worker for summaries, compaction, database queries and other high-volume agent tasks. The analysis reports a one-million-token context window, effort controls and independent gains over Haiku 4.5, including a 33% Terminal-Bench 4.0 score. Its headline price advantage is qualified by heavier token use, a fivefold price step above 100,000-token prompts, weaker factual recall than some rivals and a pre-release over-refusal bug. Several launch comparisons remain vendor or secondhand claims.
Editorial summary · Publisher article
What matters
- Artificial Analysis scored Haiku 5.5 above GPT-6 Luna on its Intelligence Index at maximum effort.
- The model uses substantially more output tokens than Luna at comparable scores.
- Anthropic also cut Sonnet cache-read prices and added API credits to some subscriptions.
Context & caveats
- Independent cost-per-task results are incomplete, arena scores were pending and some benchmark claims came from vendors or social-media reports.
Why this made the edition
The analysis combines launch details with independent evaluation results and meaningful caveats about token use, tiered pricing, hallucination, refusal behavior and pending benchmarks.
Source material