Reading room
Dwarkesh essay finds larger gains from data in small-scale pretraining experiments
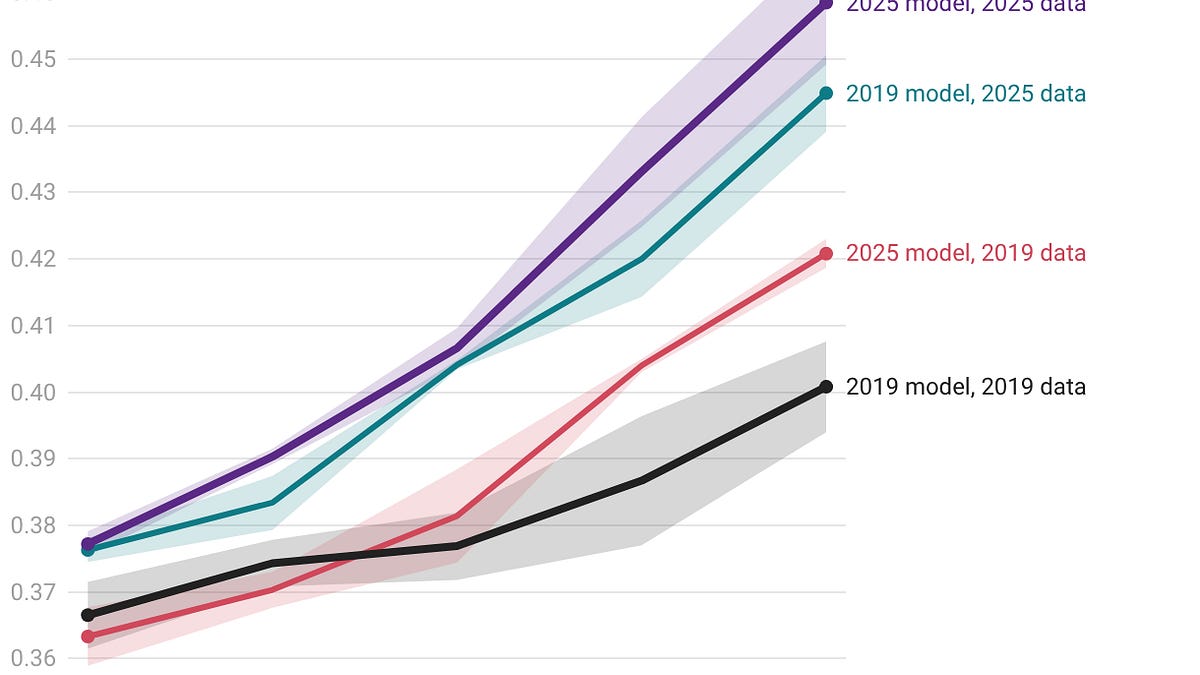
A research essay on Dwarkesh's site compares open model recipes and datasets from 2019–2025 at small training scales. At its largest tested budget, it estimates roughly 12-fold compute-efficiency gains from data changes versus 3.7-fold from model changes. The authors warn against extrapolating those figures to frontier systems: architectures also make larger runs possible, and benchmark choice strongly affects the comparison. The work concerns pretraining, not the full contribution of reinforcement learning to recent progress.
Editorial summary · Publisher article
What matters
- The experiment uses shared tokenization and context length, with OLMES downstream evaluations rather than comparing losses across different corpora.
- Synthetic-data effectiveness and frontier-scale behavior were not established by this study.
- Limited hyperparameter searches and extrapolated comparisons add uncertainty beyond the plotted error bars.
Why this made the edition
Substantive evidence supports this distinct development; selected for reader relevance and importance after comparison with published history.
Source material